
Local inference research
ANE Spike
Explore the hardware beneath local inference.
 SYSTEM ARCHITECTURE
THE PROJECT
Core ML and ggml experiments for hybrid Apple Neural Engine and Metal execution.
The work investigates where specialized inference operations can run on Apple hardware. Patch series extend the upstream llama.cpp / ggml stack with dispatch, cached Core ML programs and shared-buffer experiments. The focus is implementation and measurement rather than an unqualified performance claim.
- Core ML backend and prefill experiments
- Hybrid dispatch across hardware paths
- Shared buffers and reproducible benchmarks
Research prototype and extensions to upstream llama.cpp / ggml. Historical benchmark figures are not promoted as current product performance.
UNDER THE SURFACE
How it fits together.
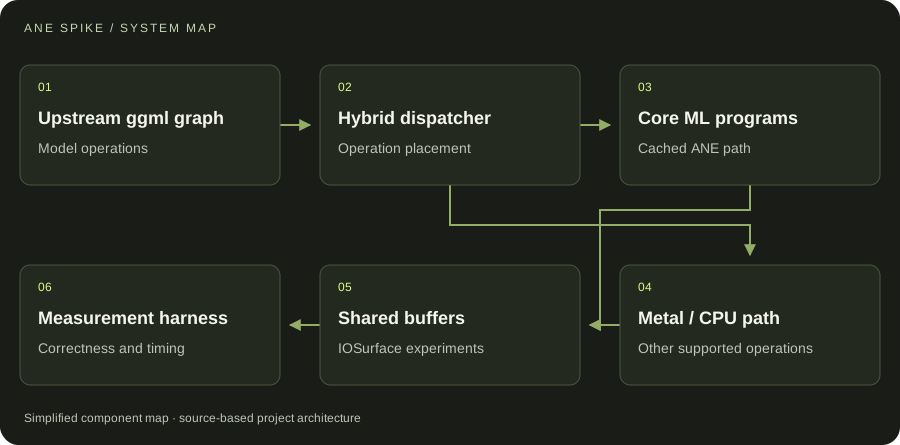
This is a conceptual view of experimental execution paths, not a single sequential pipeline. Dispatch assigns operations to the supported backend and benchmarks evaluate the result.
Swipe or scroll the diagram to inspect it. The components are also listed below.
- 01Upstream ggml graph
Model operations
- 02Hybrid dispatcher
Operation placement
- 03Core ML programs
Cached ANE path
- 04Metal / CPU path
Other supported operations
- 05Shared buffers
IOSurface experiments
- 06Measurement harness
Correctness and timing
START WITH ONE EMAIL
Need something
like this?
Tell us what you would use it for. The four lines on the right are enough to start.
There is no form to fill in and nothing to sign up for.
WHAT TO PUT IN IT
- The taskWhat is done by hand today, and how often.
- The toolsWhere the data lives: files, sheets, apps.
- The resultWhat a good outcome looks like for you.
- The timingWhen you need it.
The button opens your email app with the four questions already in the message. Examples: how to write a software brief.